Use Codex to correct a specific technical SEO failure only after the live URL, affected behavior, and production verification method are clear.
A Codex technical SEO workflow starts with a reproducible production symptom, not a request to “improve SEO.” Capture the canonical URL, status, redirect chain, robots and index directives, canonical target, rendered content, internal discovery path, and sitemap state. Then map the responsible repository layer, approve the smallest change, test it, deploy it, and repeat the same anonymous inspection. A successful code change does not by itself prove crawling, indexing, rankings, or AI citations.
This guide is the technical triage branch of the Codex cluster. It focuses on diagnosing public delivery, discovery, and rendering failures in dependency order, rather than on choosing a skill or configuring a Search Console connection.
Quick Questions
Give it the exact public URL, observed behavior, expected behavior, relevant environment details, protected areas, and the checks that prove the fix.
Not when the page has a higher dependency failure such as an error response, redirect loop, noindex directive, wrong canonical, blocked asset, or missing internal discovery path.
No. It proves local behavior only; deploy and inspect the anonymous production URL, then allow external systems time to process the change.
Technical triage order
| Question | Evidence to collect | What it does not prove |
|---|---|---|
| Does the right document load? | Status, redirect chain, final response, anonymous route check. | Indexing or rankings. |
| Can it be indexed? | Robots directives, canonical target, public content and access rules. | Google-selected canonical or inclusion. |
| Can it be found? | Sitemap URL, internal links, crawlable navigation and response paths. | Crawl timing or traffic. |
| Can it be understood? | Rendered headings, primary content, structured data parity, useful links. | AI citation or recommendation. |
Main Explanation
Start with the public route that a visitor or crawler can actually open. Record the requested URL, final URL after redirects, status code, response type, robots directive, canonical, title, visible H1, essential rendered content, and any relevant response headers. A repository can look correct while production still serves an older deployment, a host-specific redirect, a proxy error, or an empty client-side shell.
Classify the failure by dependency. Access and response problems come before indexability; indexability comes before canonical selection; canonical selection comes before sitemap and internal-link refinement; rendering and content clarity come after the correct document is being delivered. This order prevents a Codex task from polishing a page that crawlers cannot reach or that points to another URL.
Turn the finding into a bounded task. Name the affected URL and behavior, identify the likely route, controller, template, configuration, or generated asset boundary, and say what must not change. Include a local check and a production check. “Fix the canonical on this route and preserve the localized alternate links” is testable; “make all SEO better” is not.
Give Codex a verified technical SEO task
Run a free TruboRankAI audit to capture public crawl access, discovery, canonical, AI crawler, and on-page evidence before changing the repository.
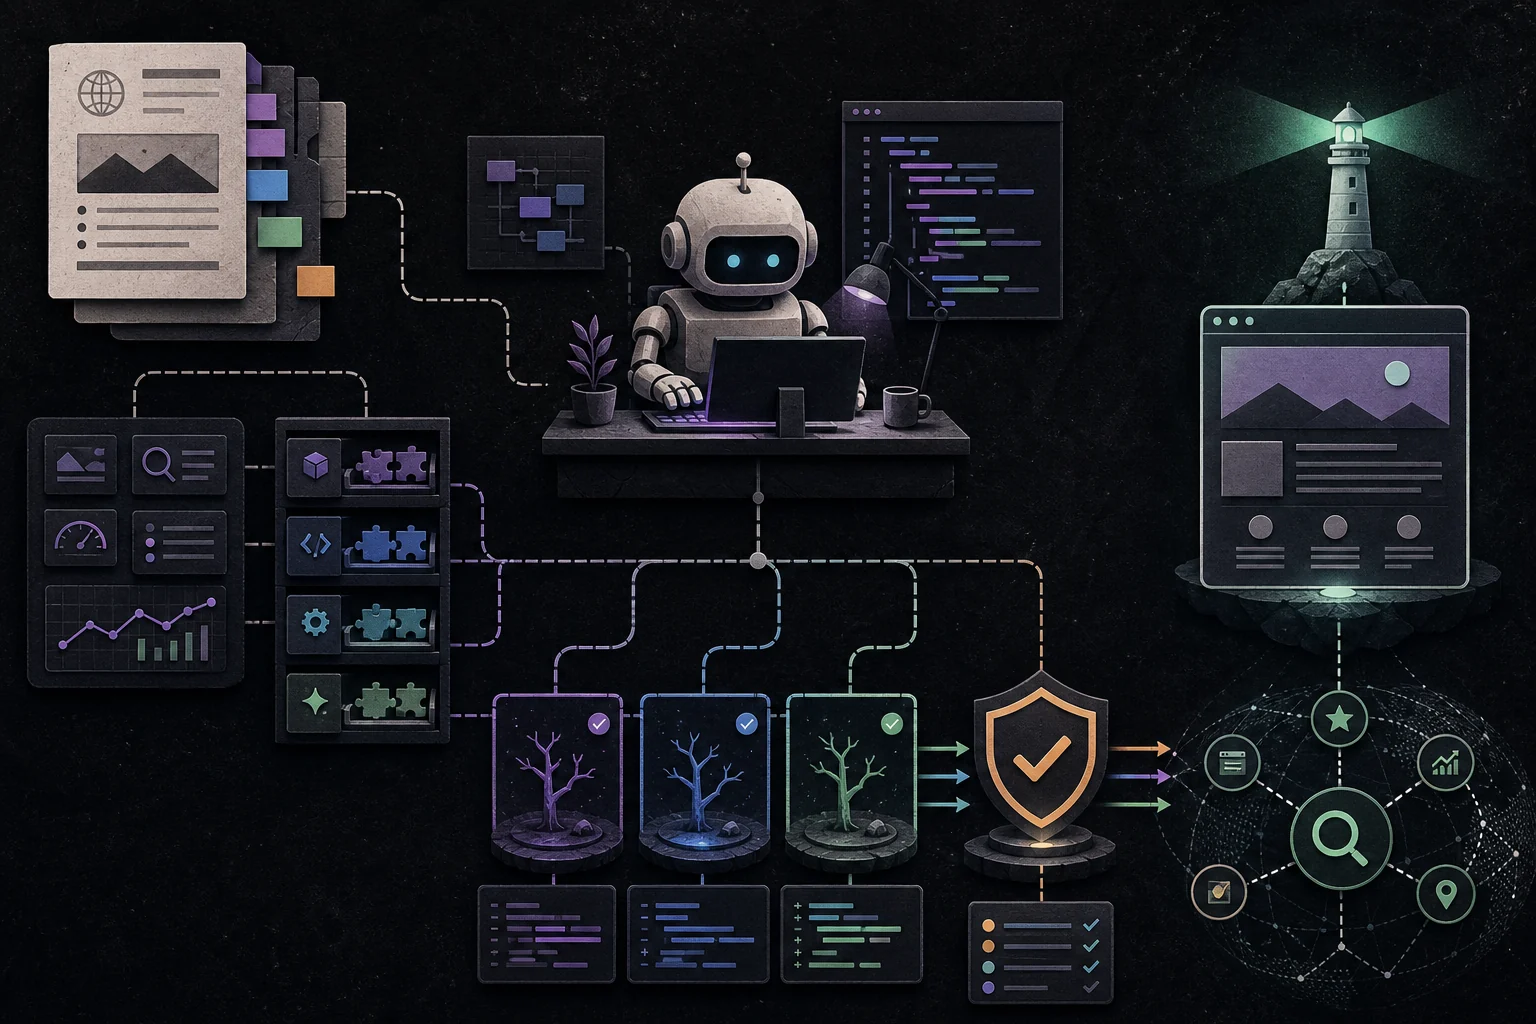
Ask Codex to map connected files before editing. A canonical can originate in a layout, a route controller, a shared helper, a CMS field, or a reverse proxy. Robots and sitemaps can be static files, generators, headers, or deployment configuration. The map should identify callers and related routes so the smallest correct change does not create a regression elsewhere.
Treat JavaScript rendering as its own evidence question. Confirm whether the important text and links are present in the response or require rendering, whether a crawler receives the same state as an anonymous browser, and whether a failed script, blocked asset, authentication gate, or API response leaves the page incomplete. Do not assume that a source file containing a heading proves that the deployed page exposes it.
Keep technical scope separate from content expansion. When a finding is a redirect conflict, an accidental noindex, a broken canonical, a blocked asset, or a missing sitemap URL, resolve that condition first. Add schema, FAQs, new copy, or further URLs only when the root delivery and discovery behavior is stable and the additional work has a distinct user purpose.
Review the diff for collateral effects. Look for route-wide metadata changes, changes to private or account pages, copied configuration, altered redirects, generated files, unsupported facts, and test artifacts. A technical fix should include only the files necessary to produce the observed behavior and its verification, with a clear note about anything that requires an environment or hosting change.
After deployment, repeat the original inspection anonymously. Compare the status, redirect, canonical, index directives, HTML, links, and sitemap entry with the evidence collected before the change. A production rescan can confirm the site now presents the intended technical signal; it cannot promise when a search or AI system will crawl, index, rank, retrieve, or cite the page.
Practical Steps
- Open the canonical production URL without an authenticated session.
- Record the response, redirect, index and canonical evidence.
- Classify the highest failed dependency.
- Map the responsible repository and deployment files.
- Define one bounded Codex task and protected areas.
- Implement and run file-specific checks.
- Review the complete diff for route and deployment side effects.
- Deploy, inspect anonymously, and rescan the same URL.
FAQ
Can Codex fix robots.txt and sitemap issues?
It can update the repository or configuration that owns those files when the scope is clear, but the deployed result and any CDN or hosting behavior still need production verification.
When should a technical SEO task create a new page?
Only when the new page serves a distinct visitor need and has a clear canonical, meaningful content, and contextual links. Technical repair alone is not a reason to add URLs.
What is the best final check?
Repeat the exact anonymous public inspection that exposed the issue, then use the appropriate first-party search or server evidence for the outcome you want to measure.
Sources and methodology
Reviewed on 2026-09-17 against OpenAI documentation for Codex workflows, AGENTS.md, and skills, plus Google guidance for rendered JavaScript and people-first content. The guide separates local implementation, deployed behavior, external crawling, indexing, rankings, and AI outcomes.
These references support the changeable facts and study findings discussed above. Results depend on each source's sample, date, market, query set, and measurement method.